
Levirge DevOps · plugin
llama.cpp
Watch a llama.cpp model server behind a firewall through the outbound devops-client: the loaded model, live token rates and slot use.
Levirge DevOps is in private testing, with no public devops-client download yet.
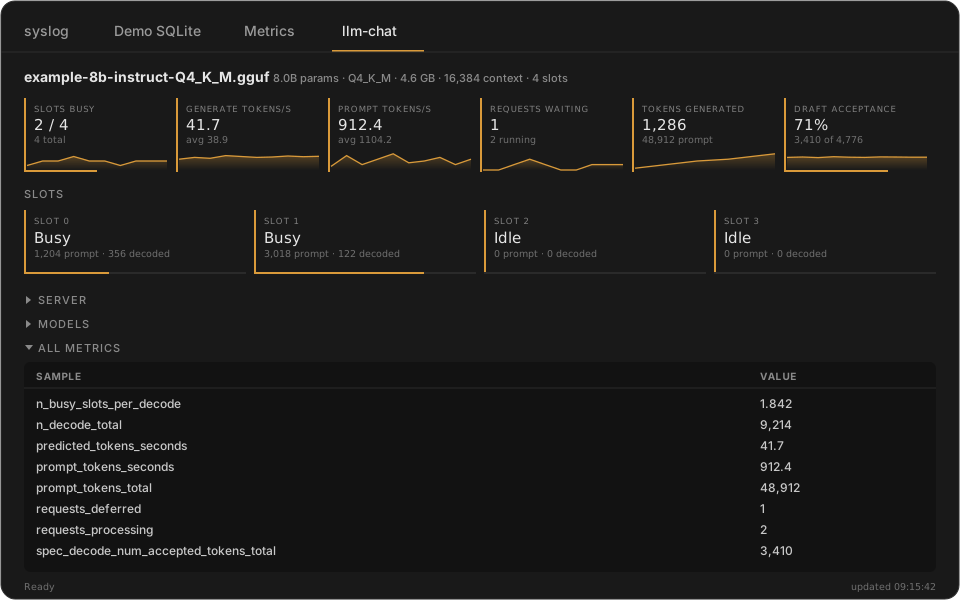
Illustrative mock-up with made-up data, not a screenshot.
Features
- Loaded model at a glance: parameters, quantization, size, context length and slots
- Generation and prompt tokens per second, with lifetime averages
- Requests waiting and tokens generated
- Draft-token acceptance for speculative decoding
- One card per slot, showing how much of its context is in use
- The same data for AI assistants through MCP (
llama_read)
Capabilities
- Reads the server's health, properties, models, slots and metrics.
Limits
- Read-only: it can't run a completion.
- Model file paths and prompt text are never returned.
- The llama.cpp server must be reachable from the machine running devops-client.
- Load tiles need the server started with
--metrics.